An hour of recorded speech transcribes to roughly 8,000 to 10,000 words. A single-day online conference with six sessions can produce a transcript longer than most published books, and almost none of it ever gets read again after the live event ends. That’s not a hypothetical. I’ve pulled the analytics on internal event archives more than once, and the pattern is always the same: a recording gets 40 views in the first week, then effectively zero after that.
The Problem Isn’t the Content. It’s That Nobody Can Find It Again.
For most of the last decade, “record the conference” meant uploading an MP4 somewhere and calling the job done. The content technically existed. Whether anyone could actually locate the specific fifteen minutes where a genuinely good answer got given was a different question entirely, and the honest answer was usually no.
This isn’t a storage problem. Storage has been cheap for years. It’s a retrieval problem, and retrieval only got solved recently, once transcription and search got good enough to trust without a human doing cleanup afterward.
What Actually Changed Here
Automated transcription used to choke on overlapping speakers, accents, and technical vocabulary badly enough that most teams didn’t bother relying on it. That’s shifted. Modern speech-to-text handles multi-speaker panels and Q&A sessions well enough now that the output is usable straight out of the box in most cases, not flawless, but reliable enough to build on.
That reliability threshold is the actual unlock, not the AI label attached to the feature. Once a transcript can be trusted, everything built on top of it, search, summarisation, topic tagging, stops being a gimmick and starts being something people actually use six months after the event instead of forgetting by Friday.
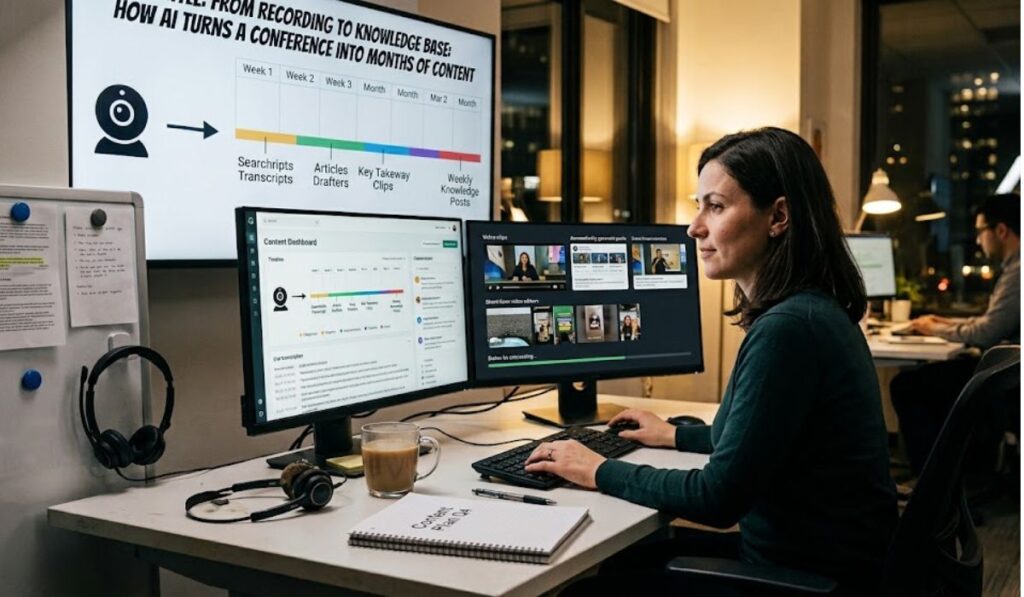
A keynote that used to produce one recording link in a follow-up email can now produce a searchable transcript, a written summary someone will actually read, a handful of short clips worth reusing, and a set of tagged moments that connect to related discussions from other events. Same source material. Considerably more usable output.
Where This Falls Short
It’s worth being honest about the limits here, because an article with zero caveats about this stuff is a press release, not an engineering assessment. Automated summarisation handles a structured keynote well. It struggles with a chaotic panel where three people talk over each other, which describes a meaningful share of the Q&A segments that are usually the most valuable part of any conference.
Topic tagging also needs some structure to actually work. Point an AI system at years of unlabeled recordings with no consistent naming convention across events, and the search results come back technically accurate and practically useless, right keyword match, wrong year, wrong context. The tool doesn’t organise a messy archive on its own. Someone still has to build the taxonomy it works against.
Why This Matters More at Enterprise Scale
For a single event, this is a nice bonus. For an organisation running regular webinars, cross-department training, and client-facing conferences across a year, it starts to look like actual infrastructure rather than a feature. The scale changes what matters in a platform choice, not just whether it can host a thousand-person call reliably, but whether the content from that call turns into something the organisation can still draw on a year later.
That’s part of why enterprise-focused platforms, https://clickmeeting.com/solutions/enterprise being one built specifically around this, approach it differently than a general-purpose video tool with a knowledge feature added as an afterthought. Administrative controls, structured tagging, and searchable archives need to be designed in from the start at that scale, not bolted onto a tool that was originally built for smaller, one-off calls.
Where This Actually Goes From Here
The bottleneck going forward probably isn’t transcription quality or summarisation accuracy. Those are mostly solved well enough already for practical use. It’s organisational discipline, whether teams actually build the tagging structure and content habits that make a searchable archive genuinely useful, instead of switching the feature on and assuming the AI will retroactively organise years of messy recordings by itself.
The tools have gotten good enough to make this genuinely worth doing properly. Whether most organisations actually put in that structural work is a separate question entirely, and it’s the one that decides whether a year of conference content quietly disappears or keeps paying off long after the event ends.

